Study date 2026-10-25. Data source: OpenRouter public API and model catalog. about 3,040 logged post-pilot calls; 3,038 with recorded cost (post-pilot study call log, including judge calls). Unpaid static page. No USDC.
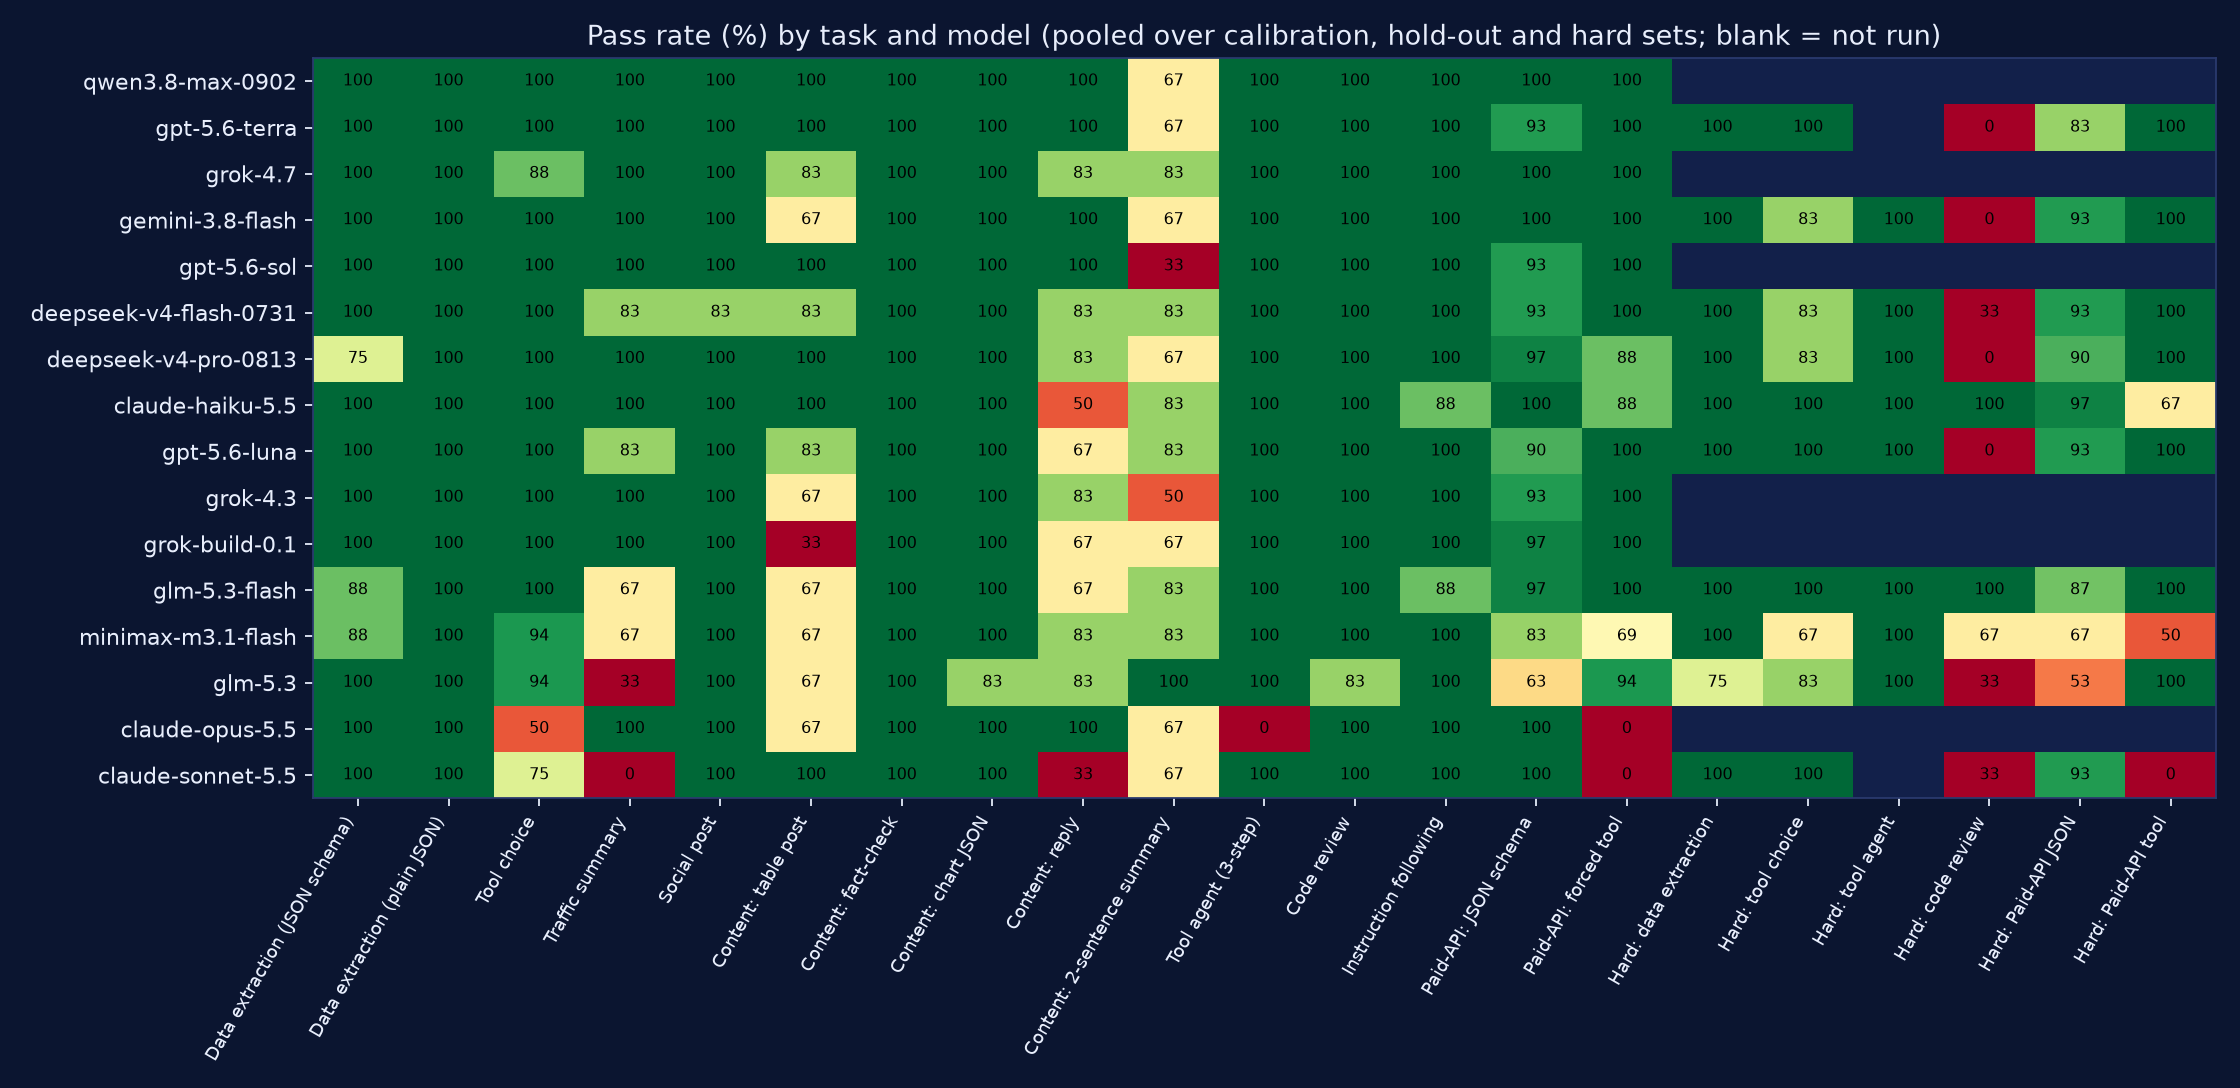
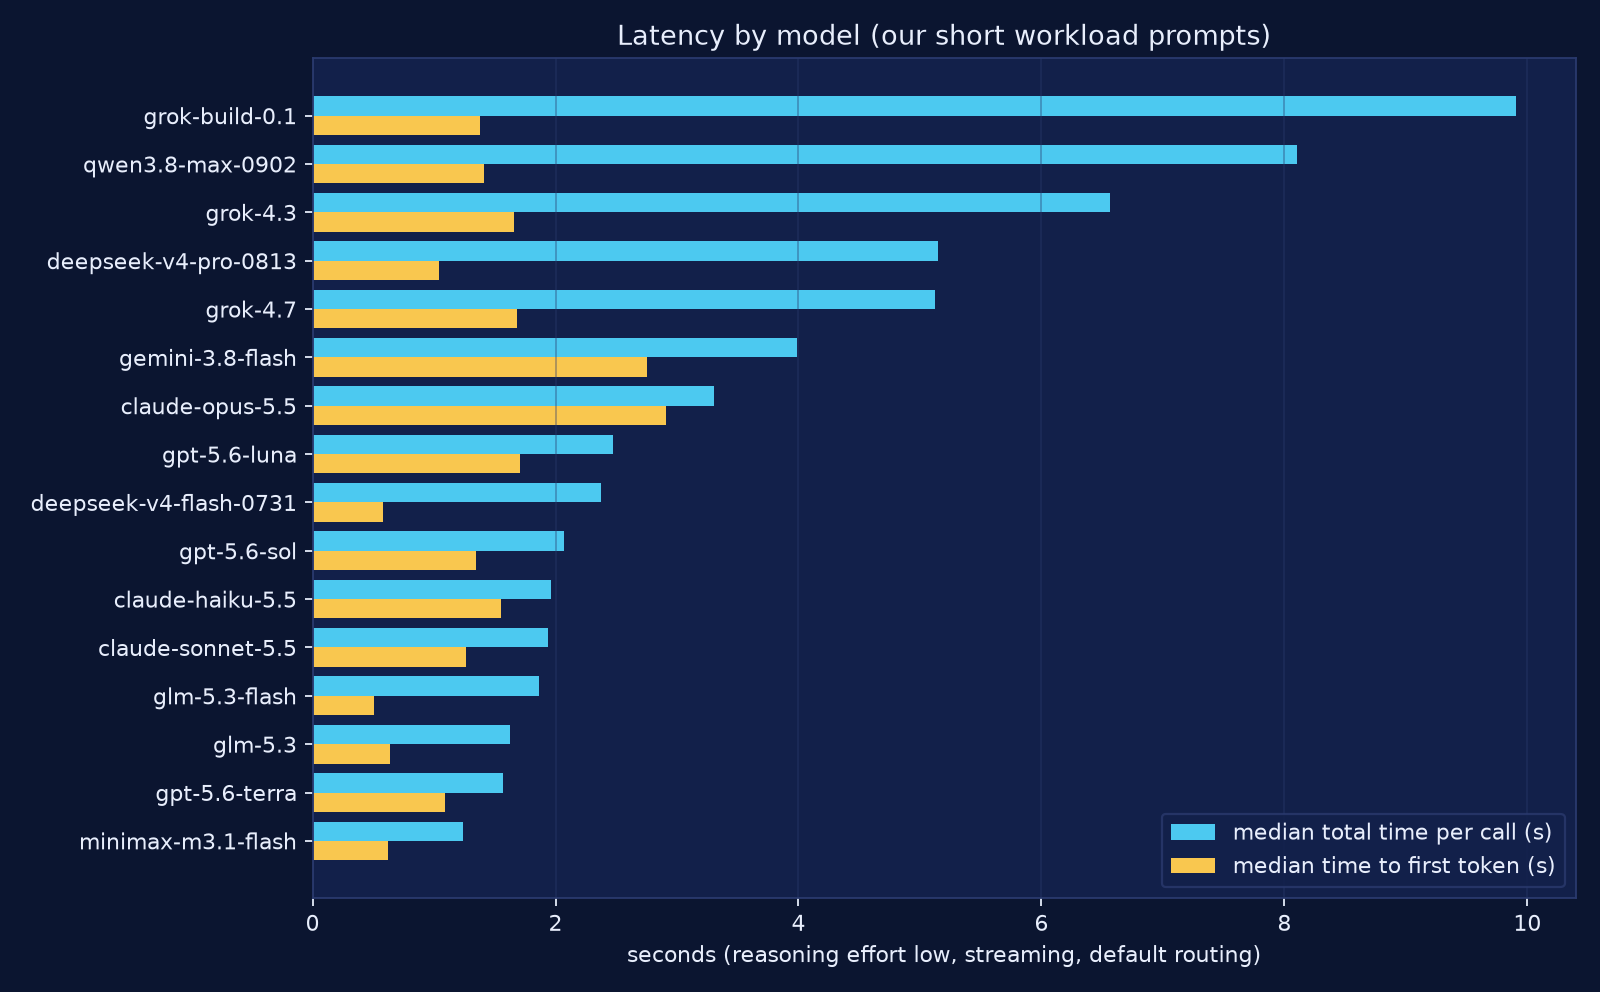
Few tasks per set. Code review used 3 snippets. One run per item (provider-default temperature). Differences under about 10 points are not significant. Hold covers 12 models; claude-sonnet-5.5, gpt-5.6-terra, claude-opus-5.5, and gpt-5.6-sol ran calibration only (and part of the hard set where noted). Prices are OpenRouter list and billed cost as of 2026-10-25. Cheap-model results are not a guarantee for other workloads. Default provider routing means billed cost follows whichever provider served each call. Latency is one time of day on short prompts and says nothing about load.
Source: OpenRouter public API (/api/v1/models catalog columns) plus live calls through that same public API. Study date 2026-10-25. about 3,040 logged post-pilot calls; 3,038 with recorded cost (post-pilot study call log, including judge calls).
16 catalog slugs in cheap, mid, premium, and premium-ref tiers. Default provider routing, reasoning effort=low where accepted, streaming, max_tokens 2,500 on workload tasks (reasoning counts toward the cap). No plugins.
Task sets: calibration (69 scored items per model, 16 models); hold (new instances of the same types, 68 items per model, 12 models); hard (harder variants, 10 models, 49 to 51 items). Tasks include JSON extraction (schema and plain), tool choice, traffic JSON summary with a fabricated-number check, short posts with length and source checks, a 3-step agent loop with mock tools, seeded-bug code review (3 snippets; the fix is executed against unit tests), instruction following, 402-body pay/skip decisions (JSON schema and forced tool call), and public-site citation or format tasks. Scoring is automatic checks (fields, executed tests, length, source, numbers, JSON validity) plus one judge model on 144 posts, replies, and summaries.
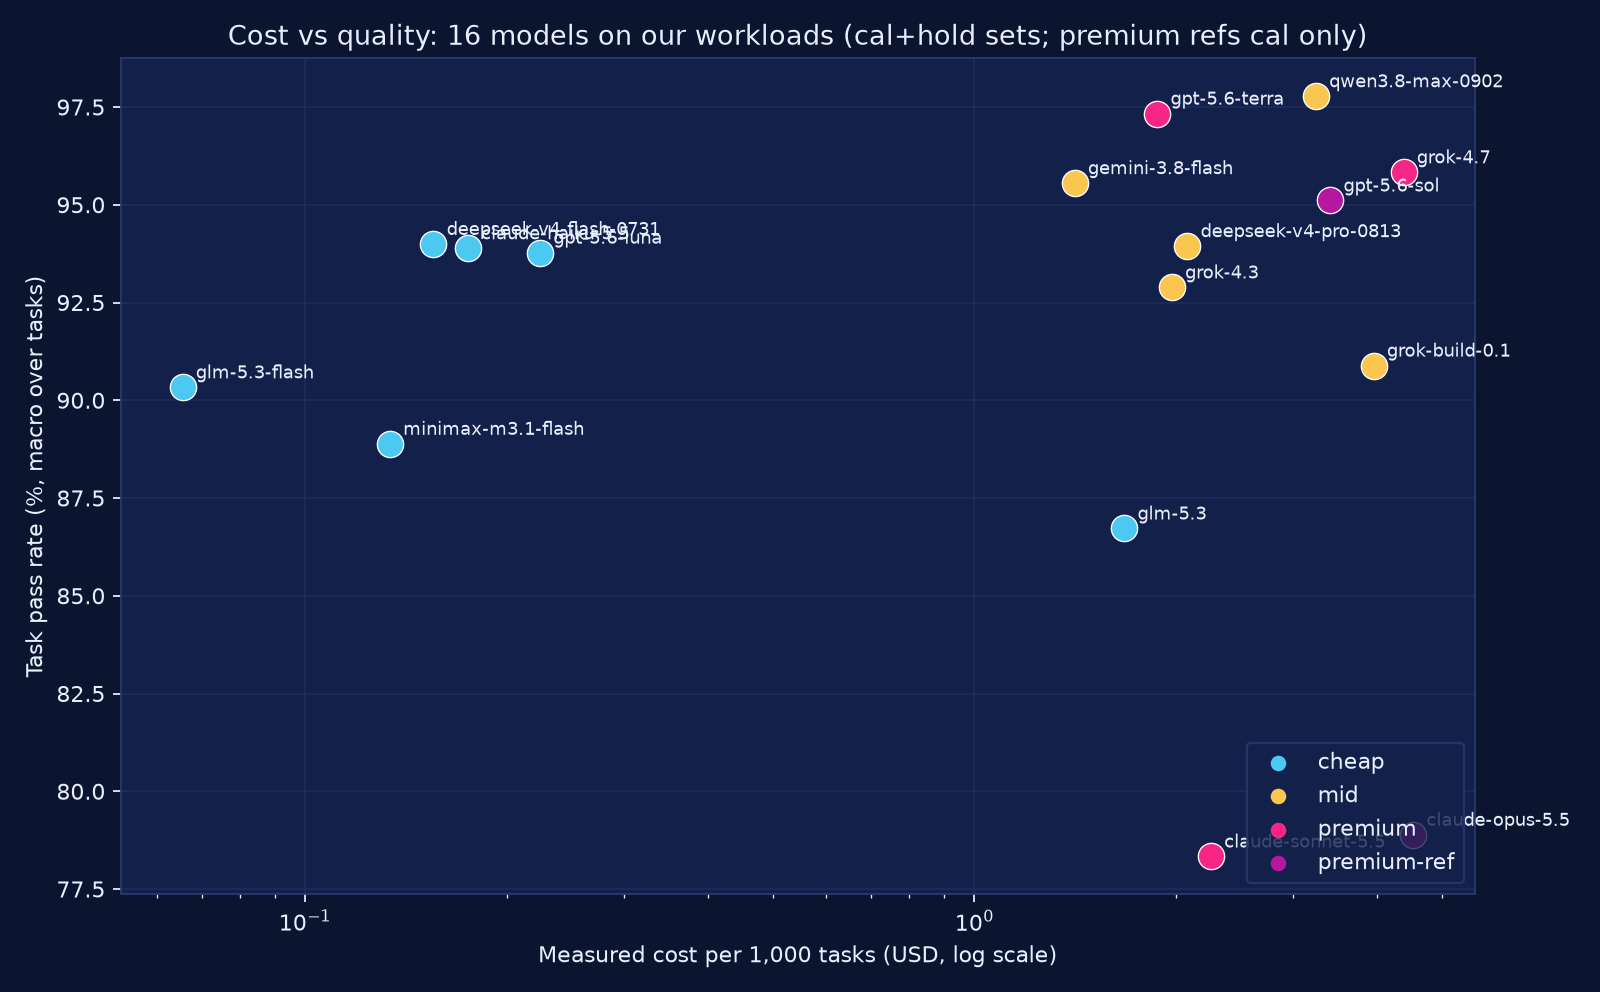
Macro score and pass rate in the table are calibration plus hold. Cost is measured billed cost per call, including reasoning tokens, times 1000, averaged over that model's calibration and hold items. p50 latency is median total seconds.
Click a column header to sort. Default order is cost per 1000 tasks, low to high. Source file: summary_models.csv.
z-ai/glm-5.3-flash |
cheap | 0.974 | 90.3% | 0.066 | 1.86 | 3 unsafe pays |
minimax/minimax-m3.1-flash |
cheap | 0.957 | 88.9% | 0.134 | 1.24 | 20 unsafe pays |
deepseek/deepseek-v4-flash-0731 |
cheap | 0.984 | 94.0% | 0.155 | 2.37 | truncation 1.7% (all sets); 2 unsafe pays; JSON valid 94.7% |
anthropic/claude-haiku-5.5 |
cheap | 0.976 | 93.9% | 0.175 | 1.96 | 5 unsafe pays |
openai/gpt-5.6-luna |
cheap | 0.982 | 93.8% | 0.224 | 2.47 | 4 unsafe pays |
google/gemini-3.8-flash |
mid | 0.991 | 95.6% | 1.413 | 3.99 | 2 unsafe pays |
z-ai/glm-5.3 |
cheap | 0.940 | 86.7% | 1.676 | 1.62 | truncation 12.7% (all sets); 4 unsafe pays; JSON valid 73.7% |
openai/gpt-5.6-terra |
premium | 0.992 | 97.3% | 1.877 | 1.57 | 5 unsafe pays |
x-ai/grok-4.3 |
mid | 0.981 | 92.9% | 1.974 | 6.56 | 1 unsafe pay; hard set not run |
deepseek/deepseek-v4-pro-0813 |
mid | 0.983 | 93.9% | 2.082 | 5.15 | truncation 1.1% (all sets); 4 unsafe pays; JSON valid 97.4% |
anthropic/claude-sonnet-5.5 |
premium | 0.894 | 78.3% | 2.258 | 1.94 | API errors 13.0%; 1 refusal; 2 unsafe pays |
qwen/qwen3.8-max-0902 |
mid | 0.996 | 97.8% | 3.241 | 8.11 | hard set not run |
openai/gpt-5.6-sol |
premium-ref | 0.988 | 95.1% | 3.404 | 2.07 | hard set not run |
x-ai/grok-build-0.1 |
mid | 0.978 | 90.9% | 3.953 | 9.91 | 1 unsafe pay; hard set not run |
x-ai/grok-4.7 |
premium | 0.984 | 95.8% | 4.381 | 5.12 | hard set not run |
anthropic/claude-opus-5.5 |
premium-ref | 0.848 | 78.9% | 4.530 | 3.31 | API errors 13.6%; 4 refusals; hard set not run |
Run on 2026-10-25 through OpenRouter's public API. Each test arm sent up to 10 sequential chat turns that share one very long fixed prompt prefix (about 100k tokens; Claude Haiku 5.5 about 80k so it stays under its 100k price tier), with roughly 350 to 700 prompt tokens added per turn (new content plus the previous answer). Each turn asks for at most 50 output tokens. Cost is the usage.cost OpenRouter returned per response. Total spend for all arms was about $0.48.
Arm types: steady means the prefix never changes. prefix edit means one early line of the prefix changes at turn 6 and stays changed (tests how a small early edit invalidates the cache).
Blended $/turn is total arm cost divided by turns completed (includes the early cache-miss turns). Expected $/turn is what the listed prices predict if every turn after the first read the cache. For the three early-stopped arms, the Blended and Expected columns are 10-turn-style projections and are not like-for-like. For the steady minimax-m3.1-flash arm, like-for-like per completed turn is 0.00496 versus the 0.00295 shown as expected. Hit rate is cached tokens divided by prompt tokens over the arm. A hit turn is a turn where at least half of the prompt tokens were read from cache (every hit in the data was 77% or more; every non-hit was at most about 0.2%).
Completed arms of glm-5.3, glm-5.3-flash, claude-haiku-5.5 at about 80k prefix, and gpt-5.6-luna read the cache on 9 of 10 turns at about 88-90% hit rate. minimax-m3.1-flash read the cache on 0 of 4 turns (steady, stopped early) and 4 of 10 turns (prefix edit). Provider switches were seen in several arms: 8 of the 13 post-turn-1 misses were switch turns, 5 were not, and 3 switches still hit. Co-occurrence only; one run each cannot show cause. These numbers describe billed cache behavior on this one run. They do not measure answer quality, and they are not a ranking of models. Three arms stopped early, so their blended $/turn is not a steady-state price and is not comparable with expected $/turn.
Click a column header to sort. Default order is the run order from the public table.
deepseek/deepseek-v4-flash-0731 |
steady | 8 | 0.00193 | 0.00060 | 62.1% | 5/8 | stopped early by a cost guard; provider switched mid-run (turn 8 was a full miss) |
z-ai/glm-5.3 |
steady | 10 | 0.00838 | 0.00803 | 89.8% | 9/10 | completed |
minimax/minimax-m3.1-flash |
steady | 4 | 0.01525 | 0.00295 | 0.1% | 0/4 | stopped early by a cost guard; essentially no cache hits |
z-ai/glm-5.3-flash |
steady | 10 | 0.00256 | 0.00432 | 87.5% | 9/10 | completed; cheaper than expected; its first turn already showed a 77% cache read (likely cross-request provider caching), which lowers the blended cost |
anthropic/claude-haiku-5.5 |
steady, ~80k prefix | 10 | 0.00177 | 0.00180 | 89.7% | 9/10 | completed; a first attempt at ~111k Claude tokens crossed the 100k pricing tier and cost 0.0695 for one turn, so it was re-run at ~80k |
openai/gpt-5.6-luna |
steady | 10 | 0.00448 | 0.00448 | 89.8% | 9/10 | completed; small cache-write premium (about $0.005 total) |
deepseek/deepseek-v4-flash-0731 |
prefix edit | 7 | 0.00328 | 0.00103 | 71.1% | 5/7 | stopped early by a cost guard |
minimax/minimax-m3.1-flash |
prefix edit | 10 | 0.00869 | 0.00433 | 39.6% | 4/10 | ran all 10 turns; hits appeared on some turns and not others; routing varied |
z-ai/glm-5.3-flash |
prefix edit | 10 | 0.00534 | 0.00554 | 79.7% | 8/10 | completed |
blended $/turn expected $/turn
Not a paid door. Not a live OpenRouter call. Not a ranking of every workload. Not auto-list. listed=true is never invented.
Static unpaid report. Numbers come from one study on 2026-10-25 using the OpenRouter public API and catalog. Prices are as of that date. Cheap-model results are not a guarantee for other workloads. listed=true is never invented. No USDC.
Open Claw Productions